Microbial Marker Gene Sequencing (16S/18S/ITS)
How it works
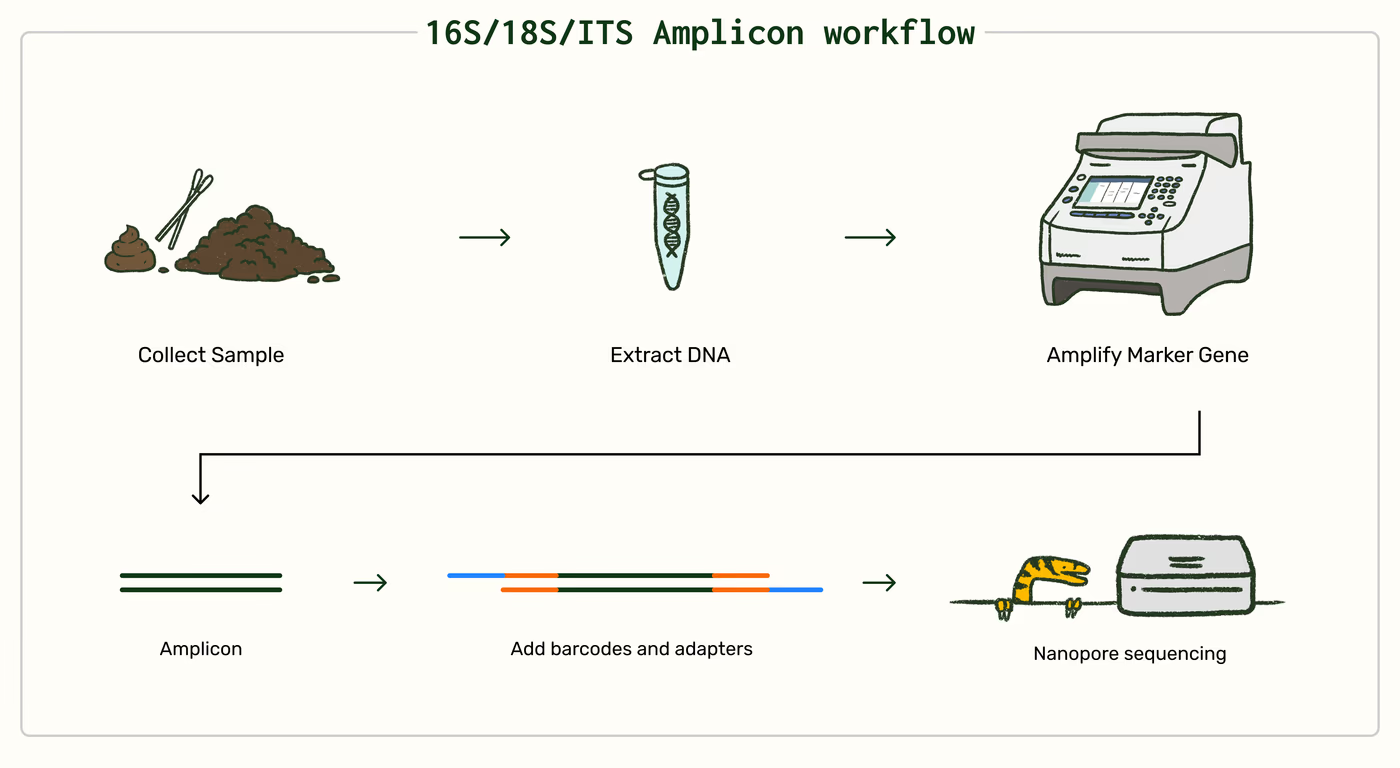
Plasmidsaurus Microbiome Marker Gene Sequencing uses Oxford Nanopore long-read sequencing to generate full-length marker gene reads and taxonomic classification for microbial community samples. Two services are available, depending on whether amplification is performed by Plasmidsaurus or by the customer: Microbiome 16S Amplification & Sequencing and Microbiome Amplicon Sequencing. Refer to the Sample Preparation Guidelines for detailed input requirements.
Microbiome 16S Amplification & Sequencing is intended for customers who have purified DNA from source material such as soil, swabs, or feces but have not yet amplified a marker gene. US-based customers may alternatively submit source material preserved in Zymo DNA/RNA Shield for on-site extraction. Plasmidsaurus amplifies the full-length bacterial 16S gene using Oxford Nanopore's 16S Barcoding Kit 24 V14 (SQK: SQK-16S114.24, Primers: 27F & 1492R).
Microbiome Amplicon Sequencing is intended for customers who have already generated their own amplicons. Samples are submitted as a purified mixture of 16S, 18S, and/or ITS marker gene amplicons generated by PCR from a microbial community sample. Barcodes are ligated directly onto the submitted amplicons, without further amplification or fragmentation.
For both services, Oxford Nanopore v14 sequencing adapters are attached and the libraries are sequenced on a PromethION P24 using R10.4.1 flow cells.
Bioinformatics
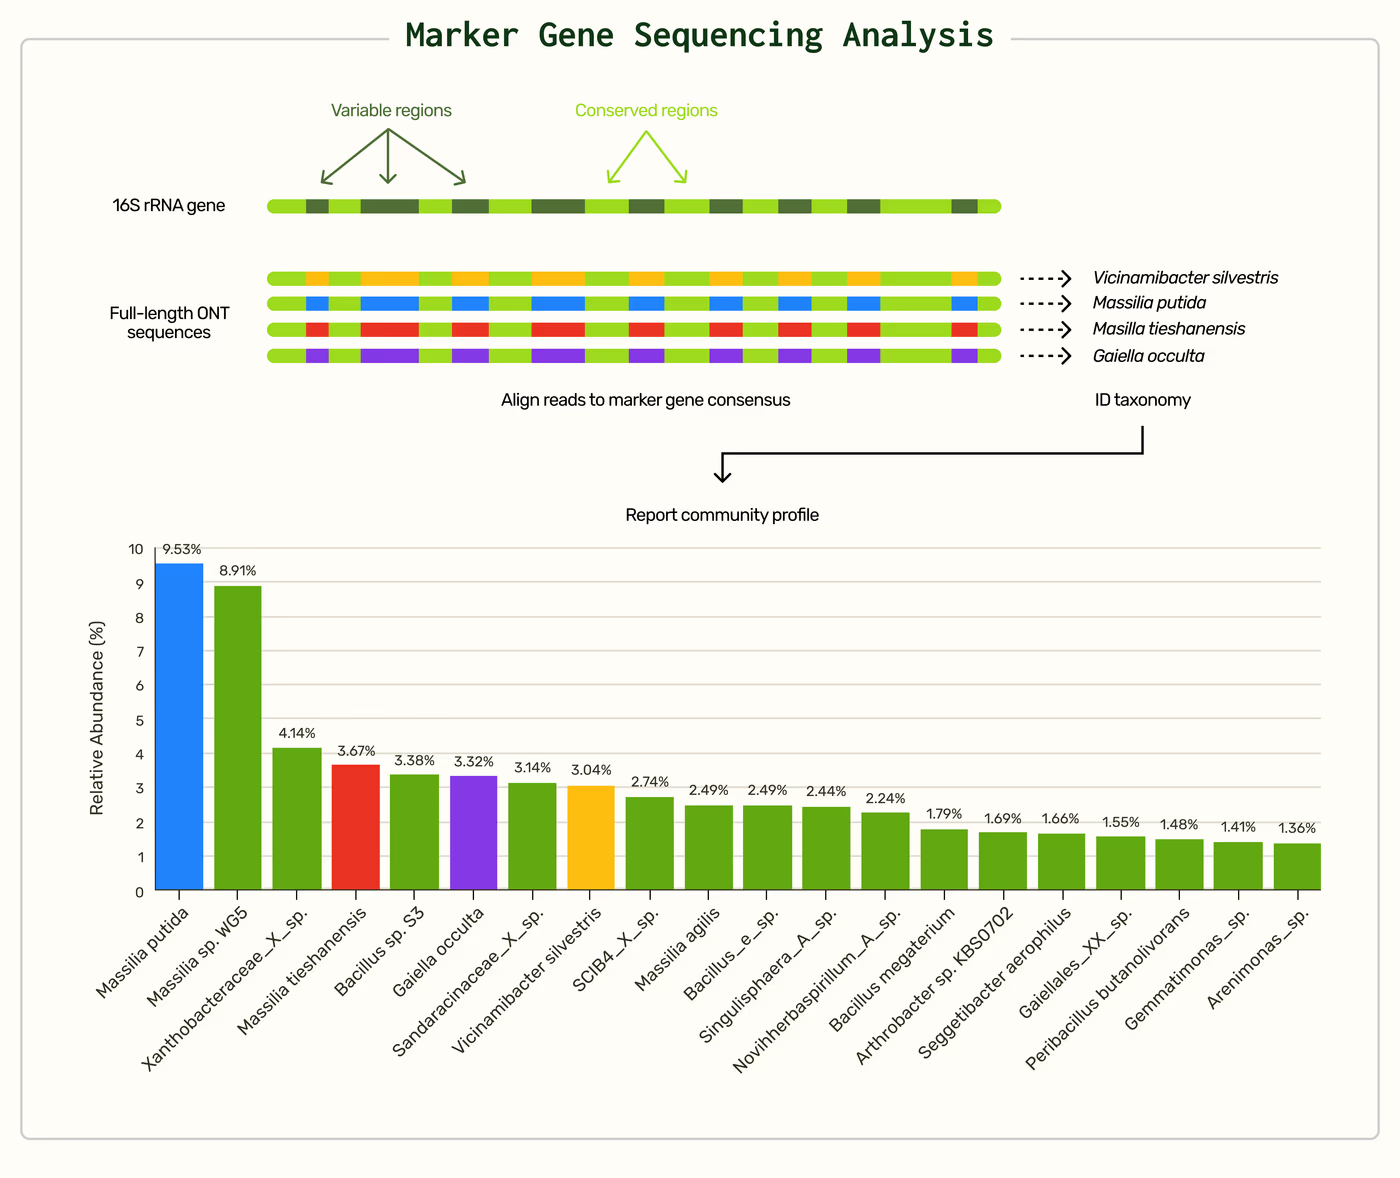
Sequencing reads are basecalled, filtered, classified against marker-gene reference databases, and summarized into sample-level taxonomic abundance results.
| Step and software | Description |
|---|---|
| Basecalling Oxford Nanopore Super accurate (SUP) basecalling model | Converts raw nanopore signal into sequence reads using Oxford Nanopore's Super accurate basecalling model. |
| Read filtering Quality and length filters | Removes reads with Qscore <10 and reads shorter than 400 bp or longer than 5,000 bp before taxonomic classification. |
| Taxonomic classification emu against rrnDB and NCBI Targeted Loci | Filtered reads are classified using emu against marker-gene reference databases to assign microbial taxa. |
| Relative abundance estimation Sample-level aggregation | Aggregates read-level taxonomic assignments to estimate the relative abundance of taxa within each sample. Taxa representing at least 0.1% of the microbial community are reported. |
Data and Deliverables
Filename key
ORDERCODEUnique order identifier, such as
JPY6QT.OSIDOrder-sample identifier, such as
JPY6QT_1, used to trace files back to a specific tube.SAMPLECustomer-provided sample name, such as
Control_rep_1. Used with the OSID in filenames like<OSID>_<SAMPLE>.
Download Results button <ORDERCODE>_results.zip
Results generated from automated data analysis pipeline.
| File or deliverable | Description |
|---|---|
<OSID>_<SAMPLE>/<OSID>_<SAMPLE>_histogram.png | Read-length histogram for the sample. |
<OSID>_<SAMPLE>/<OSID>_<SAMPLE>_ont-stats.tsv | Read stats for the sample: total reads, total bases, N50, longest/shortest read, and mean/median read length and quality. |
<OSID>_<SAMPLE>/<OSID>_<SAMPLE>_read-assignments.tsv | Species assignment for each individual read, with its confidence level. |
<OSID>_<SAMPLE>/<OSID>_<SAMPLE>_taxonomy-detailed.tsv | Same taxonomy results as the summary table, split out by confidence level (confident, high, medium, low) for each call. |
<OSID>_<SAMPLE>/<OSID>_<SAMPLE>_taxonomy-plot-genus.png | Bar chart of the most abundant genera in the sample. |
<OSID>_<SAMPLE>/<OSID>_<SAMPLE>_taxonomy-plot-species.png | Bar chart of the most abundant species in the sample. |
<OSID>_<SAMPLE>/<OSID>_<SAMPLE>_taxonomy-table.csv | Every taxon above 0.1% relative abundance, with NCBI taxonomy ID and full taxonomic ranks from kingdom to species, with the percent of reads assigned to each species. |
FASTQ button <ORDERCODE>_fastq.zip
| File or deliverable | Description |
|---|---|
<OSID>_<SAMPLE>.fastq.gz | Trimmed and filtered reads for each sample in the order. |
Online Results Page
| Deliverable | Description |
|---|---|
| Interactive species abundance chart (per sample) | Histogram or table of the top 20 most abundant species for each sample in your order. Hover over a bar in the histogram to see additional species taxonomy information. |
Technical notes and related guides
Performance and troubleshooting
Microbiome sequencing status is determined by raw read yield. Taxonomic results are not used to determine completion status. A sample is considered unsuccessful when it does not produce the minimum raw-read target for the selected service.
Although the exact cause of an unsuccessful or low-yield result cannot always be determined, the most common causes are sample inhibitors or other contaminants that interfere with PCR, library preparation or sequencing, and DNA submitted below the required concentration.
| Issue | Possible cause | Recommended action |
|---|---|---|
| Raw-data yield below the minimum target | Inhibitors or contaminants remaining after extraction | Purify with a spin column (Plasmidsaurus recommends the Zymo OneStep PCR Inhibitor Removal Kit for metagenomic gDNA), AMPure XP beads, or an equivalent method. Elute in 10 mM Tris (pH 8.5) or nuclease-free water. |
| DNA below the required 10 ng/µL, often from NanoDrop-based quantification | Quantify with a Qubit or equivalent fluorescence-based assay and submit at the required concentration. |
To support optimal sequencing results, follow the recommended Sample Preparation Guidelines for input amount, concentration, purity, and buffer conditions.
Reruns
Microbiome sequencing outcomes depend on the quantity, quality, and purity of the submitted sample. For this reason, Plasmidsaurus does not guarantee that every sample will meet the raw-read target for the selected service level.
When a sample provides adequate DNA concentration and quality but does not reach its raw-read target, we review the initial sequencing results to determine whether additional sequencing is likely to improve the outcome. Eligible samples are queued for one complimentary rerun, and data from the initial run and rerun are combined to increase the likelihood of a successful result. Rerun eligibility depends on the service level:
| Service level | Rerun eligibility |
|---|---|
| Standard | < 2,000 reads |
| Big | < 4,000 reads |
| Huge | < 8,000 reads |
| Bronto | < 200,000 reads |
If the raw-read target is not achieved after the complimentary rerun, no further complimentary reruns will be performed. Charges still apply to unsuccessful samples because library preparation, sequencing, analysis, and additional review have already been completed.
To attempt sequencing again, submit a new sample that meets all applicable sample preparation and quality-control requirements and place a new sequencing order.
For questions about sequencing results or rerun eligibility, contact support@plasmidsaurus.com.
Version Information
Document ID: PS-0003-E
Version: 1.3
Revision date: 9/22/2026