Whole Plasmid Sequencing
How it works
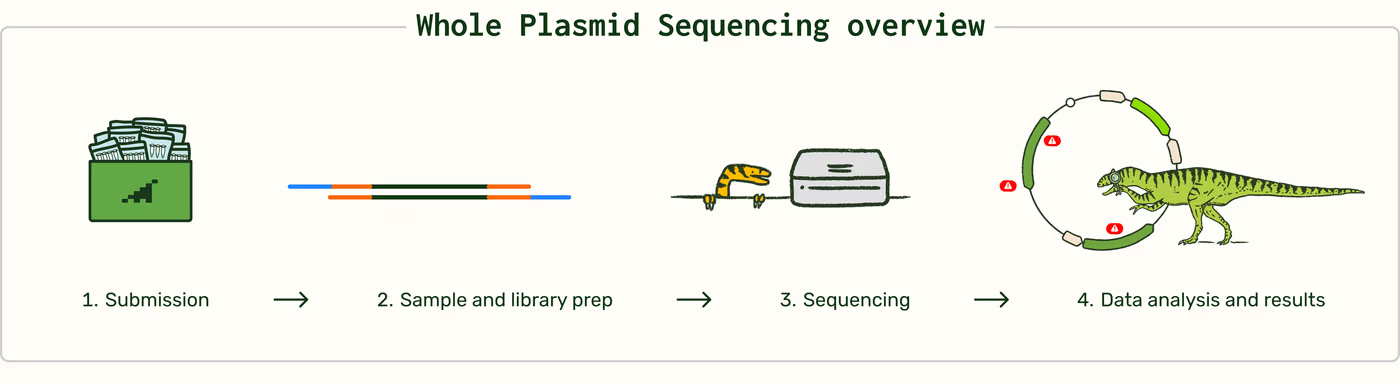
Plasmidsaurus Whole Plasmid Sequencing uses Oxford Nanopore Technologies (ONT) long-read sequencing to generate a high-accuracy, circular consensus sequence for clonal plasmids up to 300 kilobases (kb) in length.
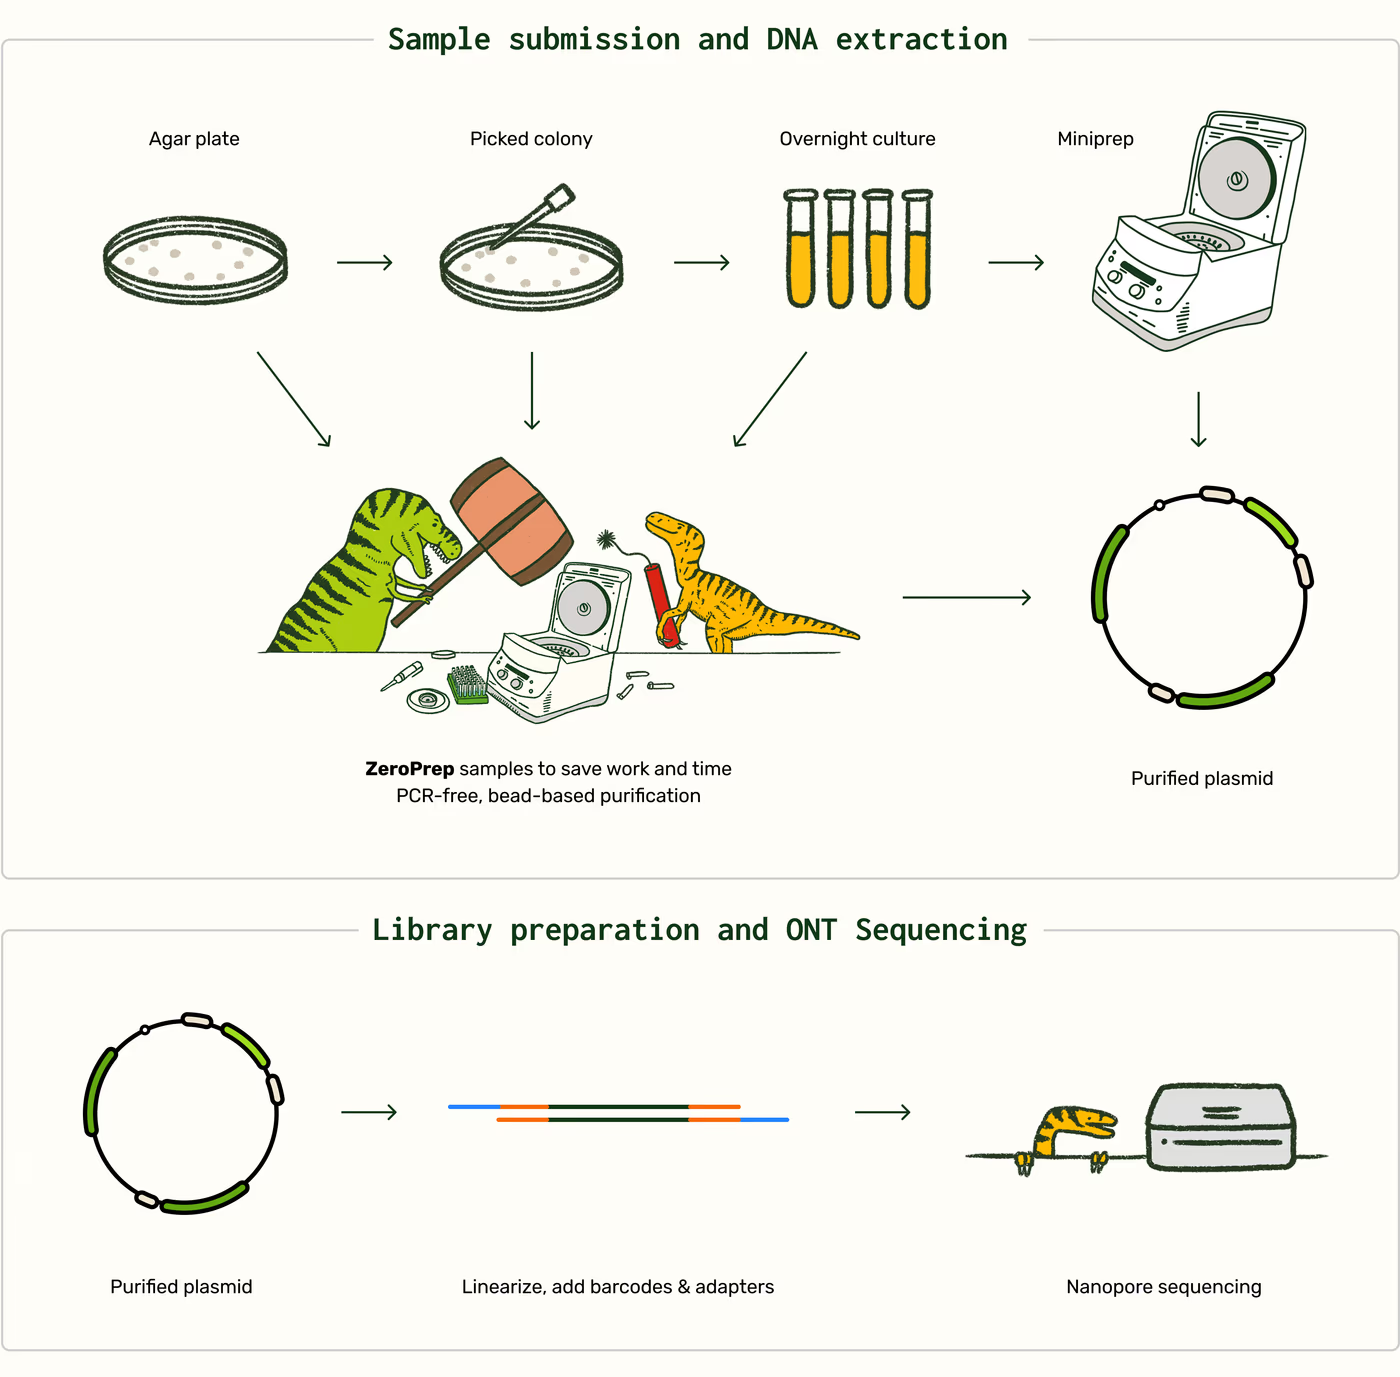
Two sample submission options are available. Purified plasmid DNA may be submitted to any of our Whole Plasmid Sequencing services. Alternatively, liquid culture, resuspended colonies, or colonies on an agar plate can be submitted to our ZeroPrep service where we perform plasmid DNA extraction prior to whole plasmid sequencing.
Refer to the Sample Preparation Guidelines for detailed sample input and submission requirements.
Purified circular plasmid DNA is linearized using a sequence-independent method and prepared as an amplification-free sequencing library using Oxford Nanopore Technologies v14 library preparation chemistry. Libraries are sequenced on the PromethION P24 platform using R10.4.1 flow cells and a primer-free sequencing workflow.
Bioinformatics
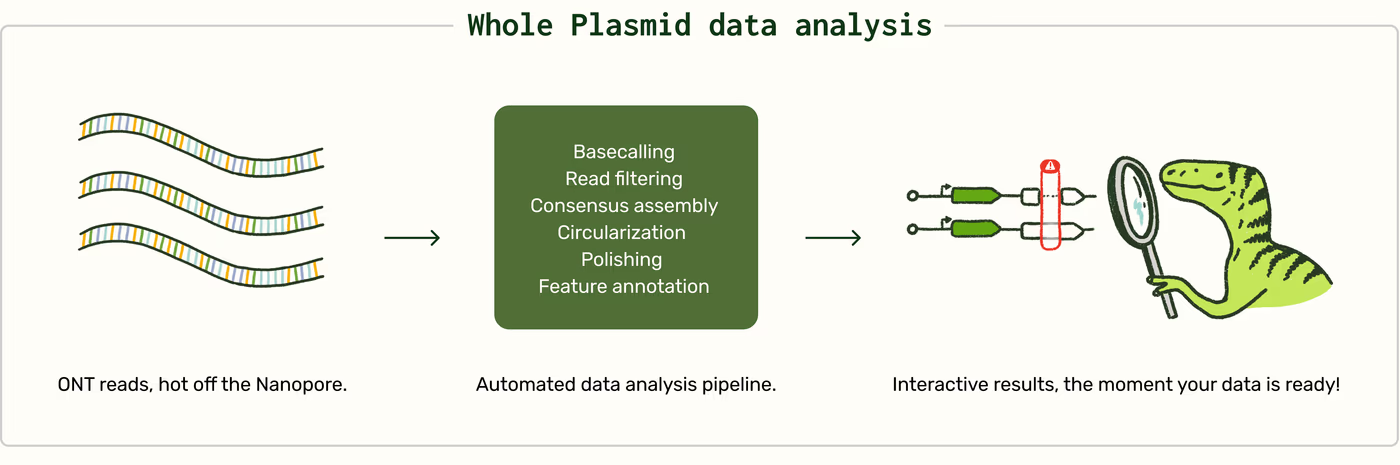
Oxford Nanopore sequencing data are processed using a proprietary analysis pipeline that performs basecalling, read filtering, consensus assembly, circularization, polishing, and feature annotation. The resulting assembly is refined into a high-accuracy circular consensus sequence.
Data and Deliverables
Filename key
ORDERCODEUnique order identifier, such as
JPY6QT.OSIDOrder-sample identifier, such as
JPY6QT_1, used to trace files back to a specific tube.SAMPLECustomer-provided sample name, such as
Control_rep_1. Used with the OSID in filenames like<OSID>_<SAMPLE>.
Download Results button <ORDERCODE>_results.zip
Results generated from automated data analysis pipeline.
| File or deliverable | Description |
|---|---|
<ORDERCODE>_gel.png | Virtual Gel Diagram. Visualization of raw-read lengths across all samples in an order, displayed in a format resembling a DNA gel. |
<ORDERCODE>_summary_files/<OSID>_<SAMPLE>.txt | Summary of consensus length, average coverage, relative molar and mass composition, total reads, total bases, and estimated E. coli genomic DNA contamination. |
<ORDERCODE>_interactive-map/<OSID>_<SAMPLE>.html | Interactive version of the pLannotate plasmid map and feature annotations. |
<ORDERCODE>_genbank-files/<OSID>_<SAMPLE>.gbk | Polished and annotated consensus sequence with a plasmid map and feature annotations generated using pLannotate. |
<ORDERCODE>_coverage-plots/<OSID>_<SAMPLE>.png | Relative sequencing coverage across the consensus sequence. Large coverage gaps or abrupt changes may indicate an assembly issue or the presence of multiple plasmid species. |
<ORDERCODE>_ab1-files/<OSID>_<SAMPLE>.ab1 | Chromatogram showing relative abundance of A, T, G, and C among raw reads aligned to the consensus at each sequence position. |
<ORDERCODE>_fasta-files/<OSID>_<SAMPLE>.fasta | Polished plasmid consensus sequence generated from the raw sequencing reads. |
<ORDERCODE>_per-base-data/<OSID>_<SAMPLE>.tsv | Position-level comparison between the raw reads and consensus sequence. Includes the consensus base, aligned-read depth, and the distribution of matches, mismatches, insertions, deletions, and individual nucleotide calls. |
<ORDERCODE>_histograms/<OSID>_<SAMPLE>.png | Read length histograms. Distribution of raw-read lengths generated from the sample. The histogram can help identify plasmid multimers, fragmented DNA, and additional molecular species. |
FASTQ button <ORDERCODE>.fastq.zip
| File or deliverable | Description |
|---|---|
<OSID>_<SAMPLE>.fastq.gz | Basecalled raw reads that align to the consensus sequence, including Phred quality scores. Reads that do not align to the consensus are excluded. |
Download CSV button
| File or deliverable | Description |
|---|---|
<ORDERCODE>-summary-report.csv | Summary of sample processing status, consensus length, and estimated E. coli genomic DNA contamination. |
Online Results Page
| Deliverable | Description |
|---|---|
| Summary Table | Sequencing results at a glance. |
| Results by Sample | Interactive plasmid map and sequence for each sample. If a reference is selected, differences to reference are highlighted. |
| Virtual Gel Diagram | Visualization of raw-read lengths across all samples in an order, displayed in a format resembling a DNA gel. |
Technical notes and related guides
Performance and troubleshooting
Samples that meet the specified DNA input requirements typically produce read counts ranging from tens to thousands, depending on plasmid size, DNA quality, and library yield. Average consensus coverage is reported in the coverage plot files; coverage greater than approximately 20× generally supports a highly accurate consensus sequence. Consensus accuracy is often greater than Q60, corresponding to an estimated accuracy of 99.9999%, or approximately one error per million bases. Most plasmid assemblies contain no errors relative to the expected reference sequence.
A plasmid sample is considered unsuccessful when the sequencing data are insufficient to generate a consensus sequence.
Although the exact cause of an unsuccessful or low-coverage result cannot always be determined, the most common cause is insufficient input (DNA for Whole Plasmid sequencing, bacterial biomass for ZeroPrep).
| Issue | Possible cause | Recommended action |
|---|---|---|
| No consensus sequence or low consensus coverage | Insufficient DNA input, often caused by inaccurate concentration measurement | Quantify DNA using a Qubit or equivalent fluorescence-based assay and submit the recommended concentration. |
| Broad or irregular read-length distribution in read length-histogram | Multiple plasmid species, fragmented plasmid DNA, or genomic DNA contamination | Prepare a clean plasmid sample from a clonal culture and minimize DNA fragmentation during extraction and handling. |
Reruns
Rerun requests for unsuccessful samples may be submitted through the Order Information page or by contacting support@plasmidsaurus.com.
Before approving a rerun, Plasmidsaurus will evaluate whether the remaining sample quantity and quality are sufficient for repeat processing. A reference sequence may also be requested to support the evaluation.
Depending on the sample, additional preparation may include:
- Measurement of DNA concentration and/or purity
- Sample cleanup using the Bead Cleanup Protocol for an additional $5 per sample
- Concentration normalization
For questions about sequencing results or rerun eligibility, contact support@plasmidsaurus.com.
Version Information
Document ID: PS-0002-E
Version: 1.2
Revision date: 9/22/2026